
 Contact
 How to shop

Delivery
Shopping guide
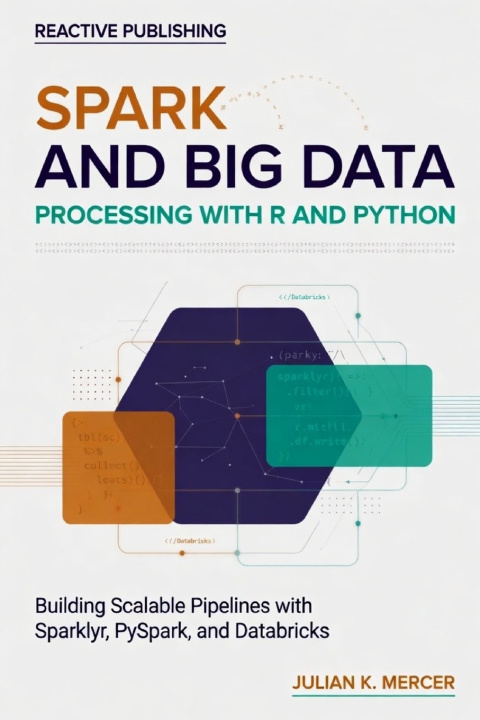
Spark and Big Data Processing with R and Python
Building Scalable Pipelines with Sparklyr, PySpark, and Databricks
 English
 86 b
 Delivery to Austria
Up to 30 days for returns
Customers also purchased


 /
 Paperback
 15.99
€

Reactive Publishing
Learn big data processing with Spark using R and Python.
This book offers a practical introduction to Apache Spark for large-scale data work. It focuses on building scalable data pipelines using Sparklyr, PySpark, and Databricks.
You will discover how to:
- Work with large datasets using Apache Spark
- Use Sparklyr to integrate Spark with R
- Develop with PySpark in Python
- Leverage Databricks for cloud-based Spark environments
- Construct reliable data pipelines for real-world use
The book bridges the R and Python ecosystems, helping data professionals use the right language for different Spark tasks. It covers core concepts including data transformation, distributed processing, and moving projects from development to production.
Written for data analysts, data scientists, and engineers who want to add Spark to their toolkit.
Perfect for: Professionals looking to expand their skills in big data processing with Spark across both R and Python.


About the book
English

Give this book today
It's easy
1 Add to cart and choose Deliver as present at the checkout 2 We'll send you a voucher 3 The book will arrive at the recipient's addressYou might also be interested in
 /
Paperback
161.69
€

 /
Paperback
54.89
€


 /
Paperback
38.79
€

 /
Paperback
36.99
€

Hi! I'm Libroamiko, your book advisor.
How can I help you?